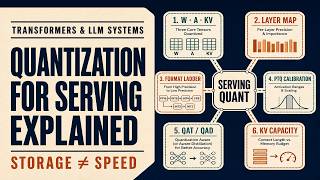
LLM Quantization for Serving (Weights, Activations, and KV Cache Quantization Explained)
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 3, 2026
Future Outlook
For 2026, Quantization Kv Cache remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Learn more about LLM inference here → ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ... 00:00 Attention Is Geometry 00:53 TurboQuant Introduction 01:02 Two Problems with Standard I implemented Google's TurboQuant paper (ICLR 2026) as a CUDA-native compression engine using NVIDIA cuTile on a ... Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The In this deep dive, we'll explain how every modern Large Language Model, from LLaMA to GPT-4, uses the The one where Unbiased Bob revisits the To produce one word, a language model has to look back at every word that came before it and run the entire stack of attention ... This video is a simple tutorial to explain what is Slides: docs.google.com/presentation/d/1bNzOJNoF8SjHoijJky1AN5TxqdQd84yIfeSVhqXEv48/edit?usp=sharing. In this AI Research Roundup episode, Alex discusses the paper: 'OScaR: The Occam's Razor for Extreme Your LLM fits comfortably in GPU memory. Then the conversation gets longer. More users arrive. And suddenly CUDA Out ... Free newsletter: multiagentacademy.substack.com/