Introduction of Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai
Looking for the latest information on Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai? We've compiled comprehensive data, records, and insights about Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai.
Important Facts
Explore the primary sources for Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai.
History
Stay updated on Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai's latest milestones.
vLLM Deep Dive: PagedAttention, Continuous Batching & 24x Throughput
How to Scale LLM Applications With Continuous Batching!
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference
vLLM Continuous Batching in Python: Serve Concurrent Users Without Static Batches
L-52: Continuous batching – vs Static Batching for LLM Inference #llm #inference
One GPU. 30 People. Zero Cloud (vLLM)
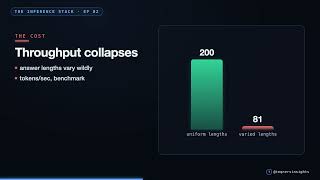
The GPU Is Mostly Waiting: Continuous Batching, Explained
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 4, 2026
Conclusion
For 2026, Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Same prompt, temperature zero, phir bhi 1000 runs me 80 Ever wondered how ChatGPT, DeepSeek, Claude, Gemini, and other Large Language Models (LLMs) can serve thousands of ... Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... Your inference GPU costs $30 an hour and works about 30% of the time. Not broken - scheduled wrong. Episode 2 of The ... cefboud.com/posts/inside-llm-inference-engine-nano- How do large language models actually work, and how do engines Want to make your Large Language Models (LLMs) run faster and more efficiently? In this video, I explain Getting a model to run and getting it to handle a hundred users are different problems. Without touching the weights or changing a ... If you want to deploy an LLM endpoint, it is critical to think about how different requests are going to be handled. In typical ... At nine in the morning, one person asks the office's local AI model to summarize a meeting, and the answer streams back faster ... When a GPU runs a language model, it spends most of its time waiting for memory, not doing math. This video explains, from the ...
Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai.pdf
What is the most accurate information about Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai.
Why is Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai trending right now?
Interest in Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai updated?
We regularly update our database with the latest information, media, and analysis related to Continuous Batching Vllm Kyun Har Jawab Alag Hota Hai.