Looking for the latest information on Continuous Batching Ais Engine? We've compiled comprehensive data, records, and insights about Continuous Batching Ais Engine.
Core Information
Explore the key sources for Continuous Batching Ais Engine.
Latest News
Stay updated on Continuous Batching Ais Engine's newest achievements.
The GPU Is Mostly Waiting: Continuous Batching, Explained
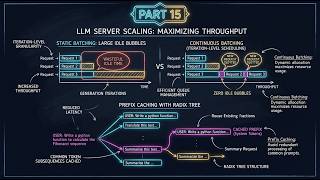
Continuous Batching & Prefix Caching Part 15
Why LLM GPUs Waste 76% of Their Capacity Continuous Batching
What's the Difference Between a Continuous and Batch Process
Batch Processing vs Continuous Processing
Deep Dive: Optimizing LLM inference
How LLM Inference Actually Scales: KV Cache, Batching & vLLM
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 5, 2026
Summary
For 2026, Continuous Batching Ais Engine remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... If you want to deploy an LLM endpoint, it is critical to think about how different requests are going to be handled. In typical ... cefboud.com/posts/inside-llm-inference- When a GPU runs a language model, it spends most of its time waiting for memory, not doing math. This video explains, from the ... How do cloud AI providers juggle thousands of simultaneous user requests without burning millions in idle GPU cycles? In Part 15 ... Why do expensive GPUs waste so much capacity while serving large language models? The problem is static Want to learn industrial automation? Go here: realpars.com ▷ Want to train your team in industrial automation? Go here: ... Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ... An LLM serves tokens on $40000 GPUs, and the bottleneck is almost never the math. It is memory and scheduling. This is LLM ...