A friendly introduction to distributed training (ML Tech Talks)
Distributed Training - All-Reduce colllective operations
What is Ring All-Reduce
NCCL Explained: How NVIDIA's GPU Communication Library Powers Distributed Deep Learning
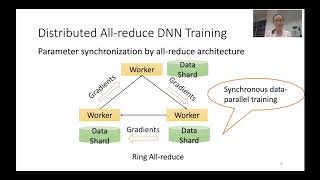
Preemptive All-reduce Scheduling for Expediting Distributed DNN Training
Distributed training on Hopsworks with collective allreduce
Networking for ML (SIGCOMM'21 Topic Preview)
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 1, 2026
Future Outlook
For 2026, Ring Allreduce remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Slides docs.google.com/presentation/d/180lS8XbeR1_bTMaldg21LKYQkjXftHuh9VnZ3xk27qQ/edit Code ... AllGather collective operation visualized by manim package. Dry run of HACKAMONTH 2026 informal paper presentation of: arxiv.org/abs/2606.20344 Abstract: --------------- Machine ... Google Cloud Developer Advocate Nikita Namjoshi introduces how distributed training models can dramatically reduce machine ... ... recvCopySend, recvReduceCopySend • Collective operations: - Yixin Bao, Yanghua Peng, Yangrui Chen, Chuan Wu. "Preemptive On Hopsworks, learn how to: 1. train a TensorFlow model using many GPUs using Hopsworks 2. how to use CollectiveAllReduce ... The paper also proposes two topologies one with optical switches and one with one