Looking for the latest information on Pruning And Model Compression? We've researched comprehensive data, records, and insights about Pruning And Model Compression.
Key Details
Explore the primary sources for Pruning And Model Compression.
Latest News
Stay updated on Pruning And Model Compression's latest milestones.
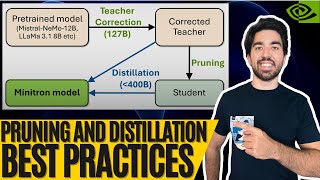
Pruning and Distillation Best Practices: The Minitron Approach Explained
AI Model Compression: Quantization, Pruning, Distillation, and Deployment
Compressing Neural Networks for Embedded AI: Pruning, Projection, and Quantization
AI Model Compression: Quantization, Pruning, Distillation, and Deployment
[CVPR2020 Oral] Multi-Dimensional Pruning: A Unified Framework for Model Compression
Pruning a neural Network for faster training times
SlimQwen: Optimizing Large MoE Model Compression Through Pruning and Distillation
What is Model Pruning
Adversarial Robust Model Compression using In-Train Pruning
EfficientML.ai Lecture 3 - Pruning and Sparsity (Part I) (MIT 6.5940, Fall 2023)
PQK: Model Compression via Pruning, Quantization, and Knowledge Distillation - (3 minutes introd...
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Summary
For 2026, Pruning And Model Compression remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io Four techniques to optimize the speed ... Ever wonder how powerful AI models can run on your smartphone? The secret is Build Your First Scalable Product with LLMs: academy.towardsai.net/courses/beginner-to-advanced-llm-dev?ref=1f9b29 ... Neural Networks and neural network based architecturres are powerful Introducing the SlimQwen framework for efficiently sites.google.com/view/saiad2021/home.