Introduction to Positional Encoding All About Llms
Looking for the latest information on Positional Encoding All About Llms? We've gathered comprehensive data, records, and insights about Positional Encoding All About Llms.
Key Details
Explore the primary sources for Positional Encoding All About Llms.
Recent Updates
Stay updated on Positional Encoding All About Llms's newest achievements.
Transformers, the tech behind LLMs | Deep Learning Chapter 5
Large Language Models (LLM) - Part 5/16 - RoPE (Positional Encoding) in AI
Positional Embedding : LLM From Scratch
How do Transformer Models keep track of the order of words Positional Encoding
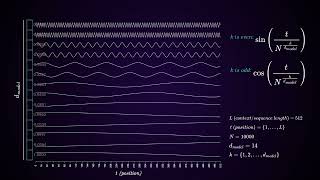
Why Transformers Need Positional Encoding | Sin & Cos Explained Visually
Positional Encoding | How LLMs understand structure
Stanford XCS224U: NLU I Contextual Word Representations, Part 3: Positional Encoding I Spring 2023
RoPE (Rotary positional embeddings) explained: The positional workhorse of modern LLMs
Positional Encoding in Transformers | Deep Learning | CampusX
Most devs don't understand how LLM tokens work
Positional Encodings and Group Theory | 3Blue1Brown and Alok Puranik
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Summary
For 2026, Positional Encoding All About Llms remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this video, I dive into the concept of What are positional embeddings and why do transformers need Breaking down how Large Language Models work, visualizing how data flows through. Instead of sponsored ad reads, these ... In this video, Gyula Rabai Jr. explains Rotary Transformer models can generate language really well, but how do they do it? A very important step of the pipeline is the ... Why can't a Transformer tell "Dog bites Man" from "Man bites Dog"? Because without In this video, I have tried to have a comprehensive look at Unlike sinusoidal embeddings, RoPE are well behaved and more resilient to predictions exceeding the training sequence length. Grant Sanderson of 3Blue1Brown and Alok Puranik, a researcher at Jane Street, work through Alok's latest blog post on