LLM Parallelism Explained: Data, Tensor, Pipeline & More
Scale ANY Model: PyTorch DDP, ZeRO, Pipeline & Tensor Parallelism Made Simple (2025 Guide)
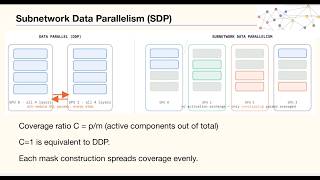
01. Distributed training parallelism methods. Data and Model parallelism
How to Scale LLMs: Flash Attention, ZeRO, & Parallelism | The Engineering Behind Massive AI Models
Mastering 4D Parallelism: Scale Your LLM Training Like Meta
Behind the Stack, Ep 12 - Model Parellism
Training LLMs at Scale - Deepak Narayanan | Stanford MLSys #83
Training LLMs at Scale #2 | Data Parallelism | ZeRO Explained
Stanford CS336 Language Modeling from Scratch | Spring 2026 | Lecture 8: Parallelism
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: September 30, 2026
Conclusion
For 2026, Llm Model Parallelism remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Slides: drive.google.com/file/d/1ht2Du3CwrZVWdyyG5-zgWznqOpWxY6VY/view?usp=sharing Peter Robinson explained ... For more information about Stanford's online Artificial Intelligence programs visit: stanford.io/ai To learn more about ... Ever wonder how gigantic foundation Part 2 of 5 in the “5 Essential Support this channel at: buymeacoffee.com/simonoz Code for animations and examples: ... Training a 7B, 7-B, or even 500B parameter The content is also available as text: ... Unlock the genius-level engineering that makes Large Language Welcome back! In this technical briefing designed for AI engineering managers and leads, we dive deep into the architecture and ... Distributed training, explained from scratch: how eight GPUs, each holding a full redundant copy of your