Looking for the latest information on Implementation Bert Llm? We've compiled comprehensive data, records, and insights about Implementation Bert Llm.
Main Features
Explore the main sources for Implementation Bert Llm.
Developments
Stay updated on Implementation Bert Llm's latest milestones.
GPT or BERT Reviewing the tradeoffs of using Large Language Models versus smaller models
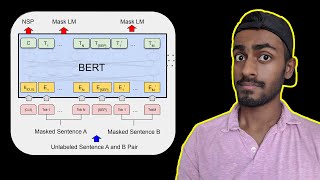
Encoder-Only Transformers (like BERT) for RAG, Clearly Explained!!!
Transformer models and BERT model: Overview
Transformers, explained: Understand the model behind GPT, BERT, and T5
Session 8: LLM Architecture - BERT
BERT and GPT in Language Models like ChatGPT or BLOOM | EASY Tutorial on Large Language Models LLM
Lecture 12.3 Famous transformers (BERT, GPT-2, GPT-3)
BERT explained: Training, Inference, BERT vs GPT/LLamA, Fine tuning, [CLS] token
Fine-Tuning BERT for Text Classification (w/ Example Code)
ModernBERT - Modern Replacement for BERT | RAG, Embeddings, Classification, Reranking
Tutorial 19 - Huggingface Transformer And Bert Implementation in Python | LLM | Generative AI
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: October 1, 2026
Summary
For 2026, Implementation Bert Llm remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Welcome back! In this video, we'll dive deep into google colab link colab.research.google.com/drive/1xyaAMav_gTo_KvpHrO05zWFhmUaILfEd?usp=sharing ... Deciding whether to use a Large Language Model or a smaller model? This video explores the tradeoffs between both ... Encoder-Only Transformers are the backbone for RAG (retrieval augmented generation), sentiment analysis and classification ... Watch this video to learn about the Transformer architecture and the Bidirectional Encoder Representations from Transformers ... Dale's Blog → goo.gle/3xOeWoK Classify text with Transformer-based self-supervised Language Models explained: ERRATA: In the "original transformer" (slide 51), in the source attention, the key and value come from the encoder, and the query ... Your team not maximizing AI? I run 1:1 and team Claude workshops for companies doing $10M+ per year: ... ModernBERT is a drop-in replacement for the original Uncover the power of Hugging Face Transformer and