Introduction of Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor
Looking for the latest information on Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor? We've researched comprehensive data, records, and insights about Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor.
Important Facts
Explore the primary sources for Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor.
Developments
Stay updated on Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor's latest milestones.
Dynamic Quantization with Intel Neural Compressor and Transformers
Optimize Your AI - Quantization Explained
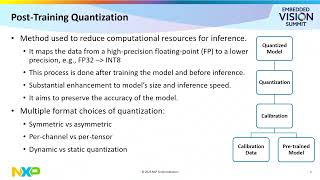
NXP Shows How to Shrink Models w/Quantization-aware Training & Post-training Quantization (Preview)
LLM Compression Explained: Build Faster, Efficient AI Models
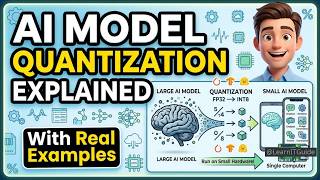
AI Model Quantization Explained: Run Large Models on Small Hardware 2026
ONNXCommunityMeetup2023: INT8 Quantization for Large Language Models with Intel Neural Compressor
Post-Training Quantization with LLM Compressor: Read and Highlighted
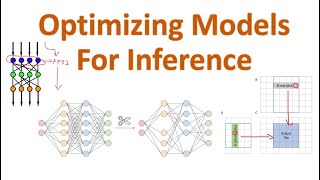
Quantization vs Pruning vs Distillation: Optimizing NNs for Inference
Quantization vs Knowledge Distillation | Which Model Compression Method Should You Choose | Uplatz
Quantization Explained: How to make AI models smaller and faster
Data is compiled from public records and verified media reports.
Last Updated: September 27, 2026
Summary
For 2026, Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
For the full version of this video, along with hundreds of others on various edge Ready to become a certified watsonx Stop worrying about GPU memory constraints. Learn how The explosive growth of large language Try Voice Writer - speak your thoughts and let How can a 70-billion-parameter LLM go from roughly 140 GB of raw weights to just 35 GB? The answer is Welcome to Module 8. This is the deployment module — the one where everything we have built over the last seven modules ...
Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor.pdf
What is the most accurate information about Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor.
Why is Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor trending right now?
Interest in Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor updated?
We regularly update our database with the latest information, media, and analysis related to Get Started Post Training Dynamic Quantization Ai Model Optimization With Intel Neural Compressor.