Distributed Training: FSDP vs DeepSpeed vs Tensor Parallelism
Model vs Data Parallelism in Machine Learning
Sora Shutdown: Free Backup Tool Saves Your Entire Library & Drafts in 5 min.
How Fully Sharded Data Parallel (FSDP) works
LLM Parallelism Explained: Data, Tensor, Pipeline & More
Sora for Social Vision With Parallel Intelligence Social Interaction in Intelligent Vehicles
OpenAI Sora: A Closer Look!
Ultimate SORA Guide 2026: How To Use Sora For Beginners
This is Sora 2
Sora for Social Vision With Parallel Intelligence Social Interaction in Intelligent Vehicles
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 27, 2026
Conclusion
For 2026, Data Parallelism Sora remains one of the most talked-about information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
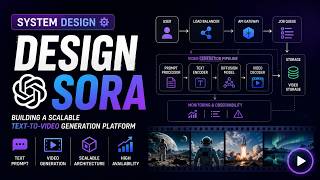
Understand the limitations of the A text-to-video service looks any other generative API: send a prompt, get back a clip. But the economics are inverted by two ... Part 2 of 5 in the “5 Essential LLM Optimization Techiniques” series. Link to the 5 techiniques roadmap: ... Expert-level comparison of distributed training strategies for large language models: PyTorch FSDP, DeepSpeed ZeRO-1/2/3, ... ... deal with this is called model parallelism and with lots of data the way we deal with this is called This video explains how Distributed Training large language models requires distributing work across hundreds or thousands of GPUs. This video breaks down the 6 ... Lambda here and sign up for their GPU Cloud: lambdalabs.com/papers sponsored by Kittl here! kittl.com/create?