About to Attention Approximates Sparse Distributed Memory
Looking for the latest information on Attention Approximates Sparse Distributed Memory? We've researched comprehensive data, records, and insights about Attention Approximates Sparse Distributed Memory.
Main Features
Explore the main sources for Attention Approximates Sparse Distributed Memory.
History
Stay updated on Attention Approximates Sparse Distributed Memory's latest milestones.
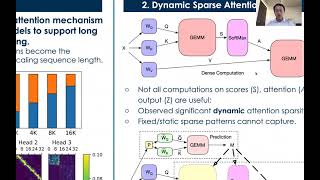
MICRO21 SRC Transformer Acceleration with Dynamic Sparse Attention
Sparse Distributed Memory (Bradford Books)
Modeling Data Streams Using Sparse Distributed Representations
What is Sparse Attention
Attention Is Getting Cheaper: Inside MLA and Native Sparse Attention (NSA)
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention
AI / Neuroscience Chat Episode 2: Basics of sparse distributed representations
Streaming Attention Approximation via Discrepancy Theory
Pentti Kanerva - Computing in Superposition in the Classical Domain
Sparse Transformers and MuseNet | AISC
Short Intro HPCA'21 SpAtten: Efficient Sparse Attention Architecture with Cascade Token/Head Pruning
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 1, 2026
Summary
For 2026, Attention Approximates Sparse Distributed Memory remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
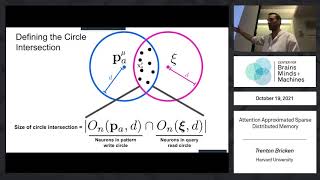
Trenton Bricken, Harvard University Abstract: While Now I want to explain this amazing article Our research intern Alex Cuozzo discusses the book Presentation by Vivek Bharadwaj (UC Berkeley) for the IPDPS'22 paper Vivek Bharadwaj, Aydın Buluç, James Demmel. This is the video of the poster "Transformer Acceleration with Dynamic In this screencast, Jeff Hawkins narrates the presentation he gave at a workshop called "From Data to Knowledge: ... Transformers hit a wall when context gets long. Paper: arxiv.org/abs/2502.11089 Notes: ... AI / Neuroscience Chat Episode 2: Basics of A Google TechTalk, presented by Ekaterina Kochetkova, 2025-10-23 ABSTRACT: The Talk by Pentti Kanerva given at a meeting of The Redwood Center for Theoretical Neuroscience at UC Berkeley. Abstract: The ... Discussion Lead: Mark Donaldson Facilitators: Florian Goebels & Michael O. Vertolli For more details including paper and slides, ... Short intro video for HPCA 2021 paper: "SpAtten: Efficient
What is the most accurate information about Attention Approximates Sparse Distributed Memory?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Attention Approximates Sparse Distributed Memory.
Why is Attention Approximates Sparse Distributed Memory trending right now?
Interest in Attention Approximates Sparse Distributed Memory has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Attention Approximates Sparse Distributed Memory?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Attention Approximates Sparse Distributed Memory updated?
We regularly update our database with the latest information, media, and analysis related to Attention Approximates Sparse Distributed Memory.